Hugging Face's logo
tags:
- object-detection
- vision library_name: mask_rcnn datasets:
- coco
Mask R-CNN
Model desription
Mask R-CNN is a model that extends Faster R-CNN by adding a branch for predicting an object mask in parallel with the existing branch for bounding box recognition. The model locates pixels of images instead of just bounding boxes as Faster R-CNN was not designed for pixel-to-pixel alignment between network inputs and outputs.
This Model is based on the Pretrained model from OpenMMlab
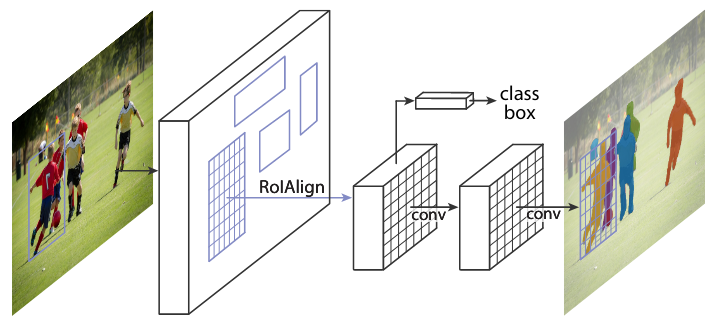
More information on the model and dataset:
The model
Mask R-CNN works towards the approach of instance segmentation, which involves object detection, and semantic segmentation. For object detection, Mask R-CNN uses an architecture that is similar to Faster R-CNN, while it uses a Fully Convolutional Network(FCN) for semantic segmentation. The FCN is added to the top of features of a Faster R-CNN to generate a mask segmentation output. This segmentation output is in parallel with the classification and bounding box regressor network of the Faster R-CNN model. From the advancement of Fast R-CNN Region of Interest Pooling(ROI), Mask R-CNN adds refinement called ROI aligning by addressing the loss and misalignment of ROI Pooling; the new ROI aligned leads to improved results.
Datasets
Training Procedure
Please read the paper for more information on training, or check OpenMMLab repository
The model architecture is divided into two parts:
- Region proposal network (RPN) to propose candidate object bounding boxes.
- Binary mask classifier to generate a mask for every class
Technical Summary.
- Mask R-CNN is quite similar to the structure of faster R-CNN.
- Outputs a binary mask for each Region of Interest.
- Applies bounding-box classification and regression in parallel, simplifying the original R-CNN's multi-stage pipeline.
- The network architectures utilized are called ResNet and ResNeXt. The depth can be either 50 or 101
Results Summary
- Instance Segmentation: Based on the COCO dataset, Mask R-CNN outperforms all categories compared to MNC and FCIS, which are state-of-the-art models.
- Bounding Box Detection: Mask R-CNN outperforms the base variants of all previous state-of-the-art models, including the COCO 2016 Detection Challenge winner.
Intended uses & limitations
The identification of object relationships and the context of objects in a picture are both aided by image segmentation. Some of the applications include face recognition, number plate recognition, and satellite image analysis. With great model generality, Mask RCNN can be extended to human pose estimation; it can be used to estimate on-site approaching live traffic to aid autonomous driving.